Bias is a test result: one audit cut AI error on darker women by up to 30 points
What the Gender Shades audit and its 2018 re-test measured, what changed once vendors were named, and what an Indian AI buyer should ask for, as of September 2026.

The original version of this piece argued that AI must balance innovation with responsibility, and cited an MIT study on facial analysis without its figures. The question a buyer actually faces is narrower: when I buy an AI product, what does “responsible” mean on a purchase order? The best evidence is that study and the re-test that followed it, so we read both.
01Naming the vendors moved the numbers
Gender Shades tested the gender classifiers sold by Microsoft, IBM and Face++ on 1,270 faces of parliamentarians, sorted by skin type. Every classifier did worst on darker-skinned women, with error rates from 20.8% (Microsoft) to 34.7% (IBM); Microsoft and IBM were best on lighter-skinned men at 0.0% and 0.3%.1 The results went to the vendors on 19 December 2017 and were published, with names, in February 2018. By the re-audit of 21 August 2018, all three had released new versions.2
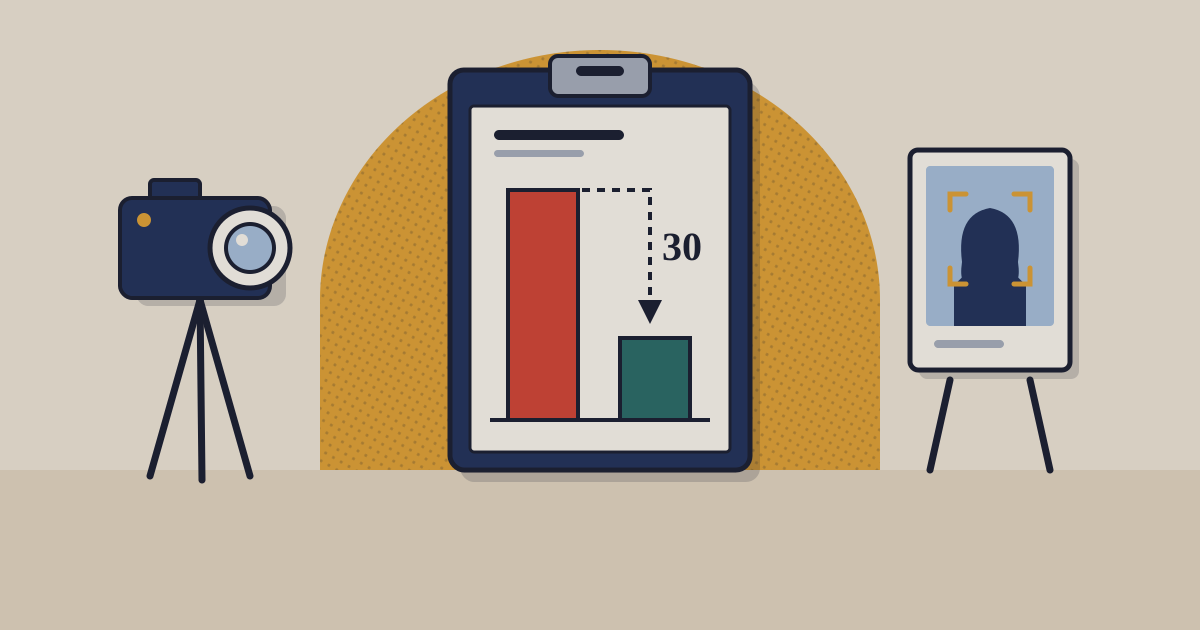
After a public audit named them, all three vendors cut their error on darker-skinned women, two of them by more than 19 points
Error rate (%) classifying the gender of darker-skinned women, Pilot Parliaments Benchmark, May 2017 audit vs August 2018 re-audit
- May 2017 audit
- August 2018 re-audit
Table view
| May 2017 audit | August 2018 re-audit | Change | |
|---|---|---|---|
| IBM | 34.7 | 16.97 | -17.7 pts |
| Face++ | 34.5 | 4.1 | -30.4 pts |
| Microsoft | 20.8 | 1.52 | -19.3 pts |
Source: Buolamwini and Gebru, Gender Shades (PMLR 81, 2018), Table 4; Raji and Buolamwini, Actionable Auditing (AIES 2019), Table 1 · as of 21 August 2018 · the same benchmark both times; the 2017 figures are from the vendors' APIs tested April to May 2017
The same re-audit tested two vendors that had not been named. Amazon got darker-skinned women wrong 31.37% of the time and Kairos 22.5%, while both scored 0.0% on lighter-skinned men.2 That is the finding worth remembering: by August 2018 the three vendors that had been measured in public had lower error on darker-skinned women than the two that had not.
02What responsibility looks like on a purchase order
None of this needs a large budget. The Fairlearn toolkit, which computes metrics like these by group, is free and open source.3 The cost is a week of an analyst’s time and a sample of your own data. A vendor that cannot produce the numbers in that week is telling you something.
03Buying it in India
India has chosen guidelines over a dedicated AI law. MeitY’s India AI Governance Guidelines, released on 5 November 2025, set seven principles, fairness and accountability among them, and leave binding rules to sector regulators.4 The binding duty for most buyers is the DPDP Act: if the AI decides about people, you are the data fiduciary, not the vendor. The Rules were notified on 13 November 2025, and the security-safeguard and breach duties apply from 13 May 2027.5 If you also sell into Europe, the EU AI Act’s prohibited practices have applied since 2 February 2025.6 Most AI products here are billed in US dollars or through a reseller, with 18% GST on top; a per-group test report should be in the quote, at no extra charge.
Sources
- Buolamwini and Gebru, Gender Shades: Intersectional Accuracy Disparities in Commercial Gender Classification, PMLR 81 (Tables 4 and 5) — February 2018
- Raji and Buolamwini, Actionable Auditing: Investigating the Impact of Publicly Naming Biased Performance Results of Commercial AI Products, AIES 2019 (Tables 1 and 2) — January 2019
- Fairlearn, open-source toolkit for assessing fairness of AI systems (MIT licence) — undated page
- MeitY, India AI Governance Guidelines, under the IndiaAI Mission, via Indian Infrastructure — 5 November 2025
- Digital Personal Data Protection Rules, 2025: notification and phased commencement — notified 13 November 2025
- European Commission, AI Act: regulatory framework and application timeline — prohibitions from 2 February 2025
Disclosure. TechBag is a software reseller: it earns a margin when a reader buys through it, including from vendors named here. The analysis is TechBag’s own; no vendor paid for or saw this piece before publication. Facts are labelled reported, TechBag count or our view.
Keep reading